Enaible – Too Much AI · 2026
Korean OCR model: fine-tuning, evaluation and release
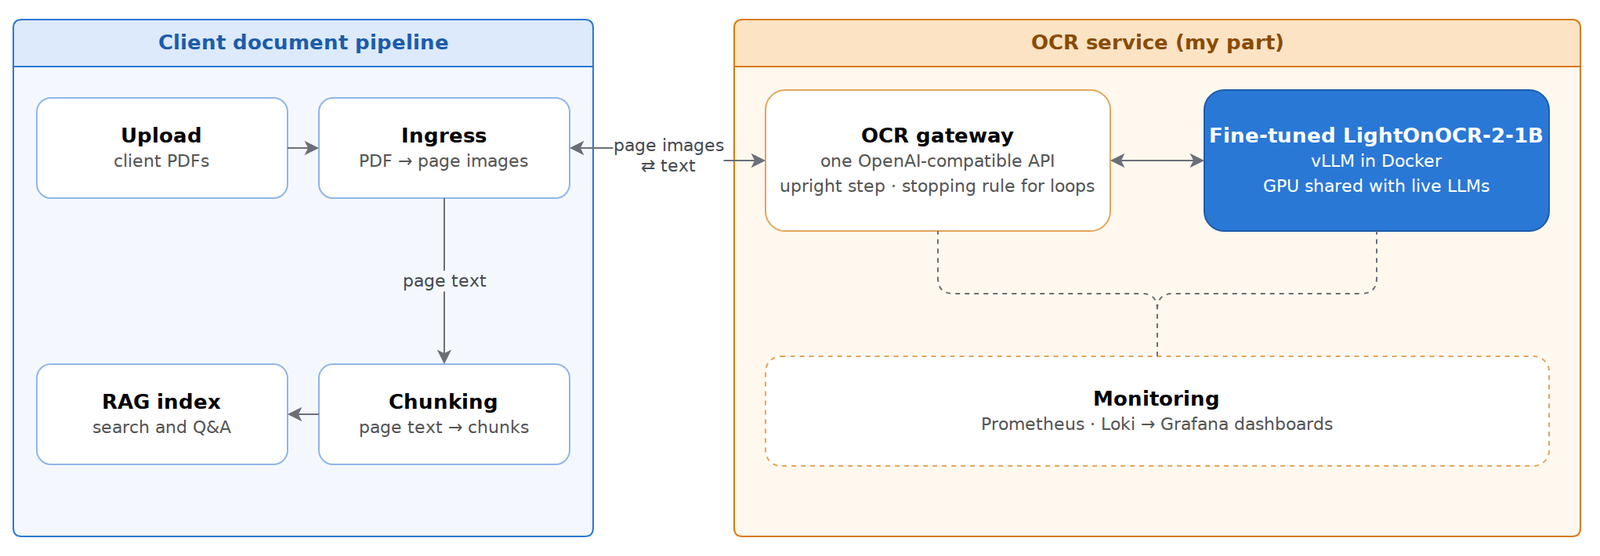
Fine-tuned a 1B vision-language OCR model (LightOnOCR, 2-1B then 3-1B with DPO) on Korean business reports and released it into a client's document pipeline for a side-by-side test against HunyuanOCR, the model in use. On 418 held-out pages the 3-1B model makes 46% fewer Korean character errors.
Read the case study
 Korean
 English
 French